I have been talking to AI for more than three years. Over 1,500 conversations, spread across four apps, and every good lesson vanished into them the moment I closed the window. This project turns that chaos into one memory I can actually search.
The idea comes from others. Andrej Karpathy wrote about keeping knowledge as a searchable wiki, and Charlie Hills showed how to turn that into a second brain with AI. I built this on those two ideas in May 2026. In August 2026 Garry Tan put his version online in full as open source; I measured part by part what it would still add to my system. The goal stayed the same: everything I have ever discussed with an AI, findable in one place and summarised into knowledge I reuse.
The reason
Knowledge that evaporates
In a good AI conversation you solve a tricky problem or nail down an approach that works. Then you close the tab, and it is gone. The next time you hit the same problem, you start over from scratch.
For me that happened four times at once. I use Claude, ChatGPT, Grok and Gemini side by side, each for something different. For more than three years the conversations piled up in four separate apps, none of them properly searchable, and not one aware of the others. Whatever I had once figured out lay scattered across four places I could not reach into.
What I wanted was simple to describe and hard to build: one place where it all comes together, where I can find back what I once figured out, and where recurring themes get summarised into knowledge I genuinely reuse.
I was not short on insights. I was short on a place where they stuck.
The approach
From loose chats to a wiki
The solution works in two layers. The first layer is the raw archive: every conversation as a separate, searchable note. The second layer is the wiki: per topic a summary that distils the essence of dozens of conversations. The first layer remembers everything, the second layer understands it.
- Collect and clean. I export the full history from each platform and automatically strip out personal data and accidentally pasted passwords before anything is stored.
- One note per conversation. Each conversation becomes a file with a short summary, keywords and links to related conversations. Trivial chats are skipped.
- Compile into knowledge. When a topic keeps coming back across conversations, it becomes a wiki page that summarises the lessons in my own words, with links back to the source.
Everything lives in Obsidian, a note-taking app that keeps everything as plain text files on my laptop. Thanks to the links between them, a map emerges on its own: you see not only which conversations belong together, but also which projects grew out of them.
Deliberately no heavy machinery. I do not have a powerful computer that can run a local AI model, and it turns out I do not need one. The whole system is plain text: searchable with simple tools, and it runs on an ordinary laptop.
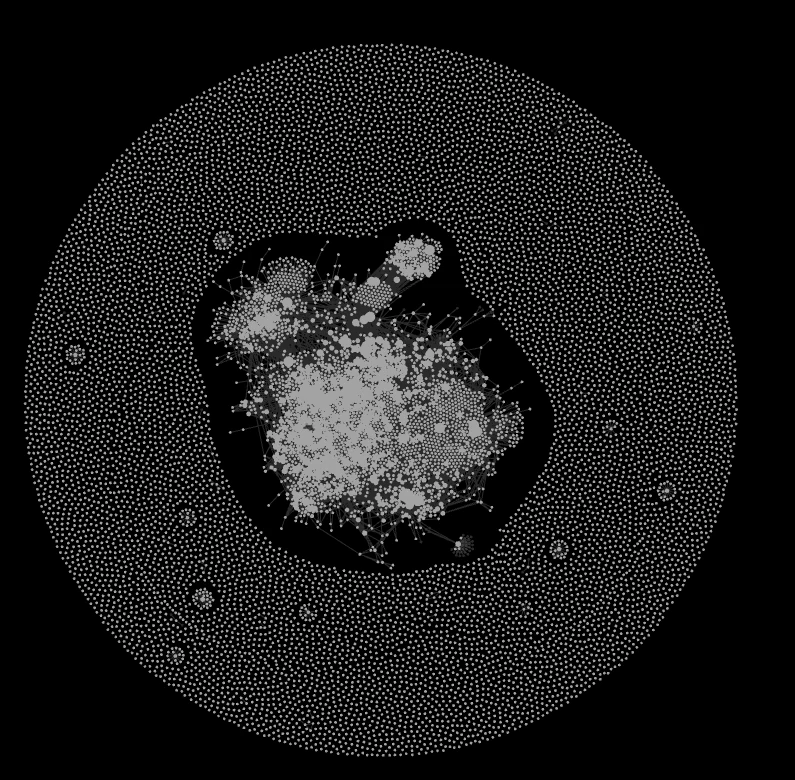
The knowledge base as a graph in Obsidian. The dense core is the compiled, interlinked knowledge. The outer ring is loose conversations still waiting for a connection.
What broke
Where it chafed
Drawing a pipeline is easy. Pushing more than three years of messy exports through it is not. Three things cost the most effort.
Scale. The Grok export alone was 730 MB. Processing it all at once stalled, so it happens in batches, with a log so a crash does not mean starting over.
Duplicates. Some platforms export your entire history again every time, including what was already in. Reprocessing blindly would fill the archive with duplicates. The fix is a check on a unique marker per conversation: already known and unchanged gets skipped, a newer version overwrites the old, only genuinely new conversations are added.
Privacy. This is my history, with everything that accidentally ends up in it. Email addresses, phone numbers and pasted access codes are stripped out automatically, and the raw archive deliberately stays on my laptop instead of in the cloud.
Personal data comes out before anything is stored.
The result
What it delivers
It is there, and it grows with every new export.
As of 2 October 2026. The archive grows with every new export, and is cleaned up the moment new material comes in.
More important than the numbers is what it makes possible. I can now ask something like "what did I figure out again about that one approach" and immediately find the spot where it was solved, with the source attached. And this archive has become the feeding ground for Kai, my AI assistant: it draws on the same knowledge base instead of starting over every time.
Borrowing and rejecting
Adopting also means saying no
The system had already been running for a few months when Garry Tan, the head of startup incubator Y Combinator, put his own second brain online in full as open source in August 2026. A fully worked-out example suddenly lay on the table: a system that updates itself automatically overnight, is searchable in several ways at once, and lays a map of connections around all your notes. Tempting to copy it wholesale. I did not.
I measured part by part whether I needed it. Two examples: one yes and one no.
- Adopted: automatic updating on arrival. As soon as I import a new export, fresh conversations are summarised and linked to the rest right away, without me having to flip a switch. But deliberately not every night on the clock. I counted how often genuinely new material actually comes in, and it turned out to be so rare that a nightly run would almost always work for nothing. So it happens at the only moment that counts: on import itself.
- Rejected: a permanently running clean-up system. In August 2026 I separately counted how many real duplicates were in my archive, and it was reassuringly few: five, out of more than thirteen hundred conversations. Building heavy machinery for so little gain is the wrong trade. I cleared out the five literal duplicates and left it at that.
That is how it went with every part I borrowed: first measure what it delivers for me, then adopt it.
The honest flip side
Never quite finished
The raw archive is up to date with the latest export. The summaries per topic always lag behind: there are always topics still waiting for a good summary.
The most important lesson is in looking things back up. An AI that answers from its memory instead of from the source makes things up. So there is a hard rule here: find the passage literally first, then answer. And "that is not in there" is a valid answer.
Sources & inspiration
Where the idea comes from
This project stands on the shoulders of three people, in two stages. At the start came Andrej Karpathy, with his idea of keeping your own knowledge as a searchable wiki, and Charlie Hills, who showed how to build a second brain with AI that grows with you. This was built on those two in May 2026. Garry Tan came later, sharing his own version in full as open source in August 2026 and showing how far you can push such a system; each of his components was measured against what was already running.
→ Andrej Karpathy - LLM-powered personal knowledge base (GitHub)
→ Charlie Hills - How I built a 2nd brain with AI (Substack)
→ Garry Tan - GBrain, an open-source second brain (GitHub)
The image at the top of this page is AI-generated (halftone paper collage). More of my AI image work is in the gallery.
Related work
More from this system
This memory doesn't stand alone: it feeds and gets fed.